

If I want to judge a change well, I need two views at once: early signals and later results. This article boils that down to 6 metrics that tell me whether people used the change, whether work got better, whether money followed, and whether risk went up.
Here’s the short version:
- Change success rate tells me if initiatives hit their stated goals.
- Adoption, time to adoption, and proficiency show whether people started using the new way of working and how fast they got there.
- Engagement and sentiment show whether people support the change or are pushing back.
- Process efficiency and quality show whether day-to-day work improved or got worse.
- Financial impact, benefit realization, and ROI show whether results turned into $.
- Risk, compliance, and change-induced issues show whether the change created new problems.
A few numbers stand out:
- Projects with strong change management met or beat goals 88% of the time, versus 13% for weak change management.
- A common adoption check uses 30-, 60-, 90-, and 180-day snapshots.
- Financial results often need 12 to 36 months before I can judge them with confidence.
What ties all six together is simple: I need a baseline, a target, one owner, a review schedule, and clear green/yellow/red rules before results come in.
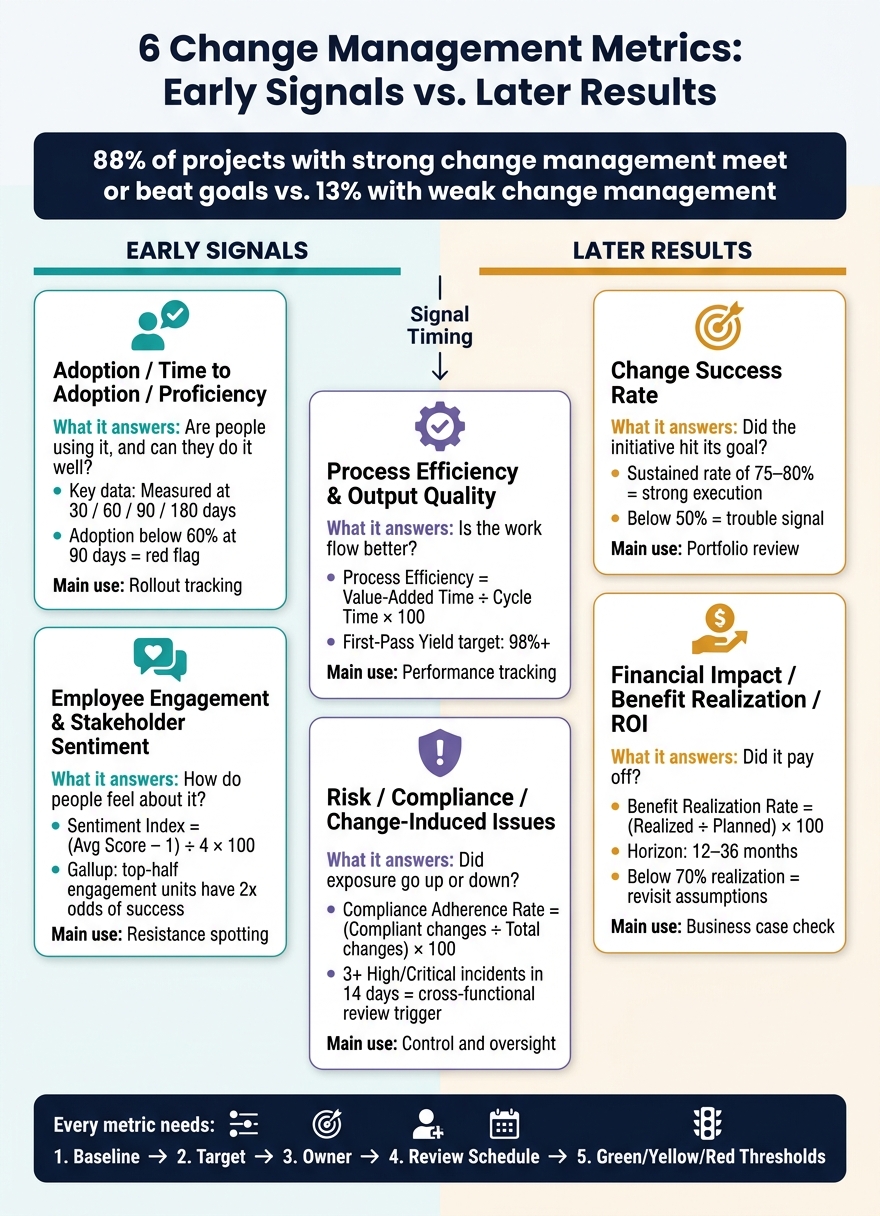
6 Change Management Metrics: Early Signals vs. Later Results
Here are the Best 6 Change Adoption Metrics & KPIs (How to Track and Measure OCM Adoption)
sbb-itb-2fdc177
Quick Comparison
| Metric | What it answers | Early or later signal | Main use |
|---|---|---|---|
| Change success rate | Did the initiative hit its goal? | Later | Portfolio review |
| Adoption / time to adoption / proficiency | Are people using it, and can they do it well? | Early | Rollout tracking |
| Engagement / sentiment | How do people feel about it? | Early | Resistance spotting |
| Process efficiency / quality | Is the work flow better? | Both | Performance tracking |
| Financial impact / benefit realization / ROI | Did it pay off? | Later | Business case check |
| Risk / compliance / issues | Did exposure go up or down? | Both | Control and oversight |
Bottom line: I’d use the first few metrics to spot rollout trouble early, and the later ones to decide whether the change was worth the cost and effort.
What Makes a Change Metric Useful
A useful change metric needs five things: a baseline, a target, an owner, a review cadence, and a decision threshold. If even one is missing, the number can turn into noise. When those five pieces are in place, it becomes much easier to judge the metrics that follow.
Tie Each Metric to a Baseline and Target
A change metric only shows progress when you know what came before. That starting point is your baseline: the documented performance level before the change begins.
Use enough past data to show normal variation, especially when a metric swings with seasonality or one-off events. If you don’t have past data, run a short diagnostic period before launch. Another option is to use a documented proxy, but be clear about its limits.
The target gives the metric direction. It should come straight from the business case and be specific enough to show whether the change worked. For example:
- Reduce error rate from 8% to 3% by 03/31/2027
- Increase CRM task logging from 30% to 75% within 12 months
Targets like "improve adoption" sound fine on paper, but they don’t tell anyone what success looks like. Put both the baseline and target into a simple scorecard or dashboard before rollout. Then check them with finance and HR so the numbers line up with business goals.
Assign an Owner and a Review Schedule
Each metric needs one owner. That person tracks the number, explains what’s driving movement, and calls out when something looks off.
The owner also needs enough proximity to affect the result. In practice, that often looks like this:
- HR for engagement
- Operations for efficiency
- Finance for ROI
- Compliance for risk
Review timing should match how fast the metric moves. Adoption and rollout metrics usually need a weekly check. Outcome metrics often make more sense on a monthly or quarterly cycle.
Set Decision Thresholds Before Reviewing Results
Set green, yellow, and red thresholds before you review results. That way, the metric leads to action instead of an argument.
Green means stay the course. Yellow means adjust training, communication, or local support. Red means it’s time for an executive-level intervention.
If you wait until after the numbers come in, bias can creep in fast. A team can always find a reason to explain away bad news. That’s why the rule should come first. For example, a company might set a threshold that if change-induced incident rates rise more than 25% over baseline for two consecutive months, the risk owner must convene a cross-functional task force within one week.
Set the rule before the data arrives.
Tell Short-Term Noise Apart From Long-Term Trend
Early dips don’t always mean the change is failing. Sometimes people are still learning, and a metric that looks rough in week two may look fine by month six.
This is where a little patience helps. Use rolling averages, such as a 4-week moving average for adoption, and compare like-for-like periods to account for seasonality. Also check for one-off events like outages, holidays, or training waves before labeling a short-term dip as a trend.
That lens matters as you read the six metrics below.
1. Change Success Rate and Goal Attainment
Metric Definition and Formula
Change success rate shows the share of change initiatives that hit their target KPI within a set timeframe.
Change Success Rate (%) = (Number of Successful Changes ÷ Total Number of Changes) × 100
A change should count as successful only if it launches within scope, avoids a major rollback, and hits its target KPI. Set that definition before rollout by using the target KPI in the business case, whether that KPI is revenue, cost, cycle time, or customer satisfaction.
Don’t just look at the average. Use four outcome bands to show how results are spread across the portfolio: fully successful (100%+), mostly successful (80%–99%), partially successful (50%–79%), and unsuccessful (<50%).
Primary Data Sources
Keep the measure tied to a small set of systems so it stays auditable. Your PMO or strategy office should hold the initiative list, along with planned and actual timelines. Finance should own the business-case targets and actual results in USD. Operational dashboards and core systems like CRM, ERP, and service platforms should supply the target KPIs linked to each initiative.
A quarterly benefits-realization review helps line up PMO status, finance results, and operational KPI data. That step matters because if those sources don’t match, the metric can get messy fast.
Short-Term Signal Value
In the first three to six months, treat this as a lagging measure. For early readouts, pair it with adoption data and early KPI movement to see if the change is moving in the right direction.
Also, compare results against the same season last year and the time-phased target curve before you treat a spike as real. A one-quarter bump can look great on paper and still mean very little.
Long-Term Decision Value
Over 12 to 36 months, this becomes a portfolio-level outcome metric. A sustained rate of 75% to 80% points to strong execution. Anything below 50% usually signals trouble in the business case, executive sponsorship, or delivery.
If the rate is weak, look at adoption and proficiency alongside it. That helps you tell the difference between a rollout issue and a strategy issue.
This outcome view works best next to adoption data, which shows whether people are using the change at all.
2. Adoption Rate, Time to Adoption, and Proficiency
If success rate tells you whether a change worked, adoption tells you whether people actually started using it.
Metric Definition and Formula
A smooth launch is nice. Sustained use is what counts. That’s where these three metrics come in: adoption rate, time to adoption, and proficiency.
Adoption rate measures how many of the people you targeted are actively using the new process, tool, or behavior during a set period.
Adoption Rate (%) = (Number of active adopters ÷ Total intended users) × 100
Before rollout, define adoption in a way people can see and measure. For example, that might mean logging a customer interaction in the CRM within 24 hours, or entering orders only in the new system. If 420 out of 500 employees meet that standard at least once a week, the adoption rate is 84%. The target should be set in the business case. A simple change may hit that mark in 30 days, while a more involved rollout may take 30–60 days.
Time to adoption tracks how long it takes users or teams to hit a set adoption threshold after launch. You can measure it as median days to first use, or as the share of users who adopt within 30, 60, or 90 days. Two rollouts can end up with the same adoption rate and still look very different. One gets there fast, the other drags. In most cases, faster adoption points to less friction and better training.
Proficiency looks past first use. It measures whether people can use the change correctly and on their own, not just try it once.
Proficiency Rate (%) = (Users meeting a defined performance standard ÷ Users who adopted) × 100
That performance standard might mean finishing tasks without errors, hitting cycle-time goals, or using the new system without help for two straight weeks. Time-to-proficiency targets often fall between 5–10 days for simple changes and 30–60 days for more involved systems.
Primary Data Sources
Use system logs and product analytics to track adoption and timing. Then pair that data with audits, checklists, or assessments to see whether people are using the change well.
That second step matters. Counting logins alone can make adoption look better than it is. Someone can sign in and still struggle through every task.
Service desk ticket volume can also help as a secondary signal. If support requests jump after go-live, that often points to a proficiency gap.
Short-Term Signal Value
In the first few weeks after launch, pay attention to early login spikes, training attendance, and adoption by team. These are leading signals. They can tell you whether the rollout message landed and whether people can access what they need.
Still, don’t read too much into one good week. Short-term adoption can get pushed up by manager pressure or plain curiosity. People may click around because the tool is new, not because the change has stuck.
Use weekly data to spot and fix rollout friction.
Long-Term Decision Value
Between 60 and 180 days, the picture should get clearer. Adoption should stay high, time to adoption should get shorter, proficiency should improve, and support tickets and errors should start to drop.
A simple way to track that progress is to measure adoption and proficiency at:
- 30 days
- 60 days
- 90 days
- 180 days
That gives you a view of both early disruption and later stabilization. If adoption stays high but proficiency remains low, that’s a warning sign. People may be using the new process because they have to, while still making mistakes or needing help. In that case, quality checks and coaching can show where support is still needed.
Adoption shows whether people are using the change. The next metric looks at how they feel about it.
3. Employee Engagement and Stakeholder Sentiment
Adoption tells you if people are using the change. Sentiment tells you if they think the change is worth it. That distinction matters most when usage is climbing, but doubt is still hanging around.
Metric Definition and Formula
Employee engagement during a change reflects how committed and supportive people are. Stakeholder sentiment shows how employees and other stakeholders feel about the change.
The simplest way to track both is with a sentiment index: a short survey with questions rated on a 1–5 scale, averaged and then converted into a 0–100 score.
Sentiment Index = (Average Score − 1) ÷ 4 × 100
Another option is percent favorable, which looks at the share of people who gave a 4 or 5. Both methods are fine. The key is to pick one and stick with it, so you can compare results over time.
Ask people if they understand the change, think it will help, and feel ready to succeed. Keep the wording exactly the same in each survey cycle. If you change the questions, you change the data.
Primary Data Sources
Pulse surveys are usually the best tool here. They’re short, frequent, and easy to act on. Pair them with input from town hall Q&A logs and customer satisfaction surveys for changes that affect customers or partners. Scores tell you where things are headed. Comments tell you why.
Manager check-ins, focus group themes, and HR ticket trends can help explain shifts in the scores. A breakdown by business unit, role type, or tenure often shows where resistance is building. Those comments can also point to teams that need a different kind of support.
Short-Term Signal Value
Right after an announcement or rollout, sentiment often drops. That’s normal. People may be unsure, bracing for more work, or getting used to something new. One low reading by itself isn’t a red flag.
What matters is what happens after that. If sentiment bounces back after clear communication and early training, the dip was likely part of the transition. If it stays low for two or more pulse cycles, that’s a sign of real resistance, not just short-term adjustment.
Long-Term Decision Value
Over time, sentiment should shift from resistance to stability as the change settles in. You want to see it level out, improve, and stay steady across teams. If scores keep falling in certain departments or manager groups, that often points to change fatigue, weak local support, or process issues that still haven’t been fixed.
Gallup research shows that business units in the top half for engagement have more than double the odds of success across financial, customer, and retention metrics compared to those in the bottom half.
That gap is hard to brush off when you’re judging whether a strategic change is sticking. If sentiment stays low in key groups, treat it as an escalation trigger, not just another number on a dashboard.
4. Process Efficiency and Output Quality
Sentiment shows how people feel about a change. Process efficiency and output quality show whether that change is working in day-to-day operations. Put simply: these metrics tell you if work is moving better, not just whether people like the new setup.
Metric Definition and Formula
Process efficiency is the share of cycle time spent on value-adding work.
Process Efficiency = (Value-Added Time ÷ Cycle Time) × 100
Cycle time is the total elapsed time needed to complete one unit or transaction from start to finish. That includes wait time and blocked time. Throughput measures how many units or transactions get completed in a set period.
To track output quality, use defect rate, rework rate, and first-pass yield (FPY).
FPY = Units Passing Without Rework ÷ Total Units
Before you measure anything, lock down your definitions. Be clear about what counts as a unit, a defect, and a rework event. If those definitions change halfway through the review, the numbers stop being dependable.
Primary Data Sources
After the metric is defined, pull it from the systems that already track the work. In most cases, the data is already sitting inside the tools teams use every day.
Common sources include:
- ERP
- CRM
- Contact center reports
- Ticketing systems
- CI/CD reports
Use monthly pulls, spot-check records, and match totals against system logs. That extra step helps catch gaps before they turn into bad reporting.
Short-Term Signal Value
In the first 30–90 days after a change, some disruption is normal. A short dip in throughput usually isn’t a red flag by itself. Rising rework or defect rates are a different story.
A control chart or simple time-series view can help here. Show weekly metrics from before and after the change. That makes it easier to see whether the process is settling down or drifting in the wrong direction.
If defect or rework rates stay high for several weeks, step in. If cycle time climbs for a short stretch and then starts to recover, that usually points to adoption friction, not a deeper process problem.
Long-Term Decision Value
Early turbulence happens. What matters more is whether the process lands in a better steady state over time.
Over 6–12 months, watch for steady gains in cycle time, throughput, and first-pass yield. Those numbers show whether the change held up after the rollout period.
There’s an important catch: speed alone doesn’t tell the whole story. If throughput goes up while defects also go up, the process is buying speed at the cost of quality. And if the process looks better but business results stay flat, check whether those gains are making it through to the bottom line.
5. Financial Impact, Benefit Realization, and ROI
Financial metrics show whether the improvement was worth the spend. Once process and quality move in the right direction, the next step is simple: did those gains turn into dollars? These three measures help answer that.
Metric Definition and Formula
Financial impact shows net dollars gained or lost against the baseline:
Financial Impact = (Incremental Revenue + Cost Savings) − (Incremental Costs + One-Time Change Costs)
Benefit realization shows how much of the planned value has actually been verified:
Benefit Realization Rate (%) = (Realized Benefits ÷ Planned Benefits) × 100
If a change initiative planned $1,000,000 in annual savings and has delivered $600,000, the benefit realization rate is 60%.
ROI compares net financial gain with total program cost:
ROI (%) = [(Benefits Realized − Program Costs) ÷ Program Costs] × 100
Use realized benefits, not projections, when calculating ROI. For example, a back-office automation project that costs $600,000 and delivers $450,000 in verified annual labor savings creates a two-year net benefit of $300,000 and a two-year ROI of 50%.
To make these numbers usable, define the baseline period, the benefit window, and which benefits count as verified and measurable. In U.S. business settings, the baseline is usually the 12 months before the change, and the benefit horizon is often 24–36 months after go-live. Apply ROI only to quantifiable, evidence-based benefits.
Primary Data Sources
This data almost never sits in one system. Finance teams usually pull from the general ledger, P&L statements, cash flow statements, and CapEx/OpEx reports. Operations teams look to ERP, supply chain, and service and support systems. Sales teams use CRM data. HR teams rely on HRIS and payroll data.
A solid benefits register connects each planned benefit to a named finance owner and a clear data source.
Short-Term Signal Value
Financial metrics are lagging indicators. They show up after operational change, not before it. In the first 3–6 months, results are often noisy because of seasonality, one-time costs, and learning-curve effects. That’s normal.
It helps to separate implementation costs from run-rate costs. It also helps to use variance bands like ±5% so teams don’t panic over routine swings. Deviations outside those bands should count as meaningful only when they continue across multiple periods.
Long-Term Decision Value
Over a 12–36 month horizon, the economics of the change should be much easier to read. Track both cumulative impact and run-rate impact. If you’re making scaling decisions, lean on run-rate figures because they reflect steady-state performance.
Compare benefit realization with the original business case. If it stays below 70% even with strong adoption, the problem may be flawed assumptions, not just weak execution. That’s usually the point where a root-cause review makes sense. And when you’re choosing what to scale, a change with strong benefit realization and low dependency risk is often a better bet than one that only shows a higher reported ROI.
The next metric checks whether the change created new risk or compliance exposure.
6. Risk, Compliance, and Change-Induced Issues
After efficiency and ROI, the next thing to check is exposure. Did the change make the business safer, or did it open the door to new problems? This metric helps you see whether a change increased or reduced risk, compliance exposure, and change-related issues.
Metric Definition and Formula
This area comes down to three core formulas:
- Risk Event Rate shows how often incidents happen compared with the amount of change activity. Risk Event Rate = Number of risk incidents in period ÷ Total changes in period
- Compliance Adherence Rate shows how many changes met policy and regulatory rules. Compliance Adherence Rate (%) = (Changes that met policy and regulatory requirements ÷ Total changes) × 100
- Issue Density tracks how many problems a change creates based on how much of the business it touches. Issue Density = Number of issues attributable to the change ÷ Number of users, transactions, or processes affected
Executives and leaders can also combine these into a single weighted Risk & Compliance Score for dashboard use.
Primary Data Sources
Use risk registers, incident logs, audit findings, policy attestations, change tickets, root-cause analyses, and training records. Incident data should sit with the risk or security team. Compliance data should sit with the compliance lead.
Short-Term Signal Value
Risk metrics often shift early because controls, behavior, and reporting don’t settle at the same pace after go-live. For complex changes, a short spike in incidents and minor findings is normal.
In the near term, severity matters more than volume. One high-severity regulatory breach means far more than a dozen low-severity issues. That’s why guardrails need to be in place before go-live. For example, more than 3 High or Critical incidents within 14 days should trigger a cross-functional review. If compliance adherence drops below 90% in the first month, that should trigger emergency training.
These early signals should lead to direct action: hotfixes, targeted audits, and fast training.
Long-Term Decision Value
Once the rollout settles down, the focus changes. Now the question is whether controls hold up over time. Across 3–4 quarters, the trend should move in the right direction: fewer incidents, steadier compliance, and lower issue density.
Regulatory and audit results are the clearest long-term signal. Fewer material audit findings, better ratings from external auditors, and a clean record with regulators all point to a stronger compliance posture.
If results keep getting worse, waiting it out isn’t the answer. The change likely needs redesign, not patience.
Tables to Make the Metrics Easier to Use
These tables help you compare measures that often get mixed together. The goal is simple: pick the main metric for each change, then pair it with a supporting metric that confirms whether the result means anything in practice.
Change Success Rate vs. Outcome KPIs
Change Success Rate shows whether the change went live the way you planned. Outcome KPIs show whether that change paid off for the business. One tells you delivery. The other tells you results. You need both.
| Metric | Formula | Data Source | Review Cadence | Leading or Lagging |
|---|---|---|---|---|
| Change Success Rate | (Successful changes ÷ Total changes) × 100% | PMO / project portfolio tool | Monthly | Lagging |
| Outcome KPI – Revenue Impact | (Actual incremental revenue ÷ Planned incremental revenue) × 100% | Financial system, CRM | Quarterly | Lagging |
| Outcome KPI – Cost Savings | (Actual savings ÷ Planned savings) × 100% | Financial system, budget vs. actuals | Quarterly | Lagging |
| Benefit Realization Rate | (Realized benefits to date ÷ Planned benefits to date) × 100% | Benefits register, finance | Quarterly | Lagging |
Adoption Sub-Metrics Compared
A strong adoption rate can look good on paper and still hide a problem. People may log in, click around, and still not do the work well. This table breaks adoption into four parts so you can see where things start slipping.
| Metric | What It Measures | Unit | Data Source | Threshold to Watch |
|---|---|---|---|---|
| Adoption Rate | % of target users actively using the new process or system | % | System access logs, activation reports | Below 60% at 90 days = concern |
| Time to Adoption | Days from go-live or training completion to first active use | Days | HRIS, system logs | Compare against a defined target timeframe |
| Core task completion | Frequency of core task completion, not just logins | % of core tasks completed per period | System usage logs, workflow tools | Sustained decline = risk |
| Proficiency | How well users perform the new way of working | Score (1–5) or % passing QA | LMS assessments, effective manager evaluations, QA checks | Average score below 3 after training = reinforcement needed |
Quantitative Engagement vs. Qualitative Sentiment
Engagement metrics show what people do. Sentiment signals show what people feel. That gap matters. If participation looks fine but comments turn sour, that’s often the point where a deeper issue starts to surface.
| Category | Metric | Measurement | Data Source | Sampling Frequency |
|---|---|---|---|---|
| Quantitative | eNPS (Employee Net Promoter Score) | % Promoters − % Detractors | Pulse survey | Monthly or quarterly |
| Qualitative | Open-text sentiment score | Coded positive / neutral / negative from survey comments | Employee surveys, town halls | Quarterly |
| Qualitative | Key sentiment themes | Thematic coding (e.g., trust, workload, career impact) | Interviews, focus groups | Quarterly or as needed |
Process KPIs by Category
This grouping helps cross-functional teams look at trade-offs without talking past each other. For example, a short-term jump in cycle time may be acceptable if it leads to a later drop in cost per transaction. That’s the kind of trade you want to spot early, not after the dashboard turns red.
| Category | Metric | Unit | Data Source | Typical Target | Short-Term Effect | Long-Term Effect |
|---|---|---|---|---|---|---|
| Efficiency | Cycle time | Hours or days | ERP, workflow tools | Reduce by a defined percentage within 6 months | May rise during learning curve | Should fall if process redesign works |
| Efficiency | Throughput | Units per hour or day | ERP, MES | Increase by a defined percentage | May dip at go-live | Should recover and improve |
| Quality | Defect rate | % or defects per 1,000 units | QA system, MES | Less than 1% of total output | May spike post-change | Expected to decline with new standards |
| Quality | First-pass yield | % of outputs passing QA without rework | QA system | 98% or higher | Temporary dip is common | Sustained improvement signals process stability |
| Customer | On-time delivery rate | % | ERP, CRM, logistics | 98% or higher | Variability during transition | Should improve with streamlined processes |
| Financial | Cost per transaction | USD (e.g., $12.50 per order) | Financial system, activity-based costing | Reduce by 15% over 12 months | May increase during implementation | Should decline if automation succeeds |
When operating gains are supposed to turn into dollars, use the next table to check whether the business case still stands.
Financial Metrics Side by Side
All figures should use U.S. currency format. The decision rule is direct: accept if NPV > $0 and BCR > 1.0; reject or revisit if either falls below those thresholds.
| Metric | Unit | Time Horizon | Best Use | Common Pitfall |
|---|---|---|---|---|
| ROI | % (e.g., 35%) | 1–3 years | High-level comparison across projects | Ignores timing of cash flows |
| NPV | USD (e.g., $2,400,000) | 3–5 years | Determines whether the change creates net value | Sensitive to discount rate assumptions |
| Benefit-Cost Ratio (BCR) | Ratio (e.g., 1.8:1) | 3–5 years | Quick relative-value signal | Doesn’t show absolute dollar value |
| Cost Savings | USD per year (e.g., $750,000 per year) | Ongoing | Tangible benefit for cost-focused strategies | May exclude indirect or one-time costs |
| Revenue Impact | USD (e.g., $3,000,000 per year) | Ongoing | Core measure for growth-oriented initiatives | Attribution to the change can be difficult to isolate |
After efficiency and business value, the next check is exposure. A change can improve speed or cost and still create trouble somewhere else.
Risk and Compliance Issues by Severity, Frequency, and Business Impact
Use this table to sort issues by severity, frequency, and business impact so teams know what needs attention first.
| Issue Type | Severity Level | Frequency Metric | Business Impact | Primary Data Source | Mitigation Priority |
|---|---|---|---|---|---|
| Security incident | Critical | Events per period | Regulatory exposure, financial loss, reputational damage | Incident log, risk register | Immediate |
| System downtime | High | Hours of unplanned downtime per period | Revenue loss (USD), SLA breach | IT monitoring, change tickets | Urgent |
| Process defect | Medium | Defects per period | Rework cost, customer impact | QA system, defect register | Scheduled |
| Compliance finding | Critical / High | Findings per audit cycle | Regulatory penalty, audit rating | Audit reports, policy attestations | Immediate |
How to Build an Executive Dashboard From the Six Metrics
After you define the six metrics, the next step is simple: decide how executives will see them in one place. An executive dashboard should answer three questions fast: Is the change on track? Where is risk going up? Is the business getting value yet? That means showing only the metrics leaders need, on the right schedule. Use the six metrics above as the framework: monthly leading indicators for rollout health and quarterly lagging indicators for business results.
Pick a Small Set of Monthly Leading Indicators
Leading indicators move fast after a change, which makes them useful for monthly reviews. Focus on adoption, time to adoption, proficiency, sentiment, and early signs of process friction. These metrics shift soon enough to help teams make course corrections before the quarter ends.
Put plainly: monthly indicators show whether the rollout is moving; quarterly measures show whether the strategy is paying off.
Add Quarterly Outcome Measures
Quarterly measures show whether those early signals turned into business results. Track process efficiency, benefit realization, ROI, and risk trends. Give the data time to settle before making hard calls. In most cases, you’ll want to look at two to four quarters of movement before drawing firm conclusions.
A good rule of thumb is to use about 60% leading indicators and 40% lagging indicators. That way, the dashboard works more like an early warning system and less like a rearview mirror.
Use Thresholds and Status Flags
Once you’ve picked the metric mix, keep the status rules the same every month. Set green, yellow, and red thresholds before the review, using the baseline and target from the business case.
For example:
- Adoption below 60% at 90 days = red
- Adoption between 60% and 79% = yellow
- Adoption at 80% or above = green
Each red status should also trigger a preset action. That might mean pausing the rollout, adding staff, or revising the plan if a metric stays red for two straight months. This keeps leaders from arguing about definitions in the meeting and pushes them toward a consistent response.
Check Dashboard Results Against the Original Business Case
Once the dashboard is live, leaders should compare current results against the original business case. Every metric on the dashboard should tie back to a specific assumption in that case.
Say the business case projected annual cost savings. The quarterly financial panel should show realized savings to date against that projected figure in U.S. dollars, not just an isolated number. That gives leaders context, which is what they need.
Positive variances, like faster adoption or better-than-expected efficiency gains, can point to room for expansion. On the other hand, if ROI or quality keeps missing the mark while adoption looks fine, that’s a sign to dig deeper. The problem may be execution, or it may be that the original assumptions were too optimistic.
Conclusion
Taken together, these six metrics show something simple but important: Did people adopt the change? Did it improve performance? Did it pay off? This isn’t six separate scorecards. It’s one body of evidence.
Use leading indicators to watch adoption and sentiment as the change rolls out. Then use lagging outcomes to check value, quality, and compliance. Put side by side, the six metrics line up with the four lenses used across this article: people, process, financial, and risk.
Treat the six metrics as one evidence set, not a ranking. Each one answers a different question about the change. Together, they give executives a clearer read on whether to stay the course, adjust execution, or rethink the strategy before small gaps turn into expensive problems.
Before the next review, compare all six metrics against the baseline and the business case. If the pattern backs up the case, keep going. If it doesn’t, make changes now. Use the baseline and business case as the final check before deciding whether to stay the course or change direction.
FAQs
Which metric should I start with?
Start with usage and engagement metrics tied to the people side of the change. They show whether employees or customers are actually using the new process or tool.
Focus on a few early signals:
- Usage rates
- Training participation
- Time to proficiency
These are often the first signs that the change is starting to stick. Over time, they may lead to compliance, productivity, and performance results.
How do I set baselines and targets?
Start by documenting your current state with historical data. Include seasonality so your baseline is clear and you’re not comparing July to December like they mean the same thing. That one step can save a lot of bad calls later.
Create a KPI dictionary too. Everyone should use the same definitions, formulas, and data sources. If one team says “conversion rate” and another means something slightly different, things get messy fast.
Set targets with the SMART framework. It also helps to phrase each target with an action-object-outcome-timeframe structure so it’s plain and specific.
Keep a 70% leading / 30% lagging mix. That way, you’re not just staring at results after the fact. You’re also tracking the signals that show where things are headed.
And for each metric, assign one clear owner. If everyone owns it, no one owns it.
What if adoption is high but results are weak?
High adoption with weak results usually means employees are using the new system or process, but it still isn’t leading to the business outcomes you expected.
At that point, take a closer look at three things: the strategy itself, how well employees can use the new approach, and whether your metrics are set up to track the value the change was supposed to deliver.